A failed deployment rarely arrives with a clean explanation. An engineer moves between build logs, a change request, monitoring, and messages from the team before deciding what to do. AI can help assemble that context, but the same access becomes dangerous when a plausible explanation is allowed to trigger an unchecked production action.
The useful question is where assistance reduces investigation time without weakening the delivery process. This guide uses an illustrative subscription service to examine build analysis, release preparation, incident support, and carefully bounded remediation. It separates work a model can draft from decisions the delivery system must enforce. The goal is an operating model a small team can maintain, with clear evidence, permissions, and a practical way to stop or reverse a change.
Key takeaways
- Start with diagnosis and preparation before production writes.
- Measure investigation and correction time together.
- Keep deployment authority in explicit controls outside the model.
Find a specific bottleneck in the delivery process
Map a recent release from the first code change to production verification. Record where people waited, repeated a search, or copied information between systems. The best initial use case is often a narrow information task: grouping related build errors, summarizing a change, or finding the owner of a failing dependency. These jobs have visible inputs and an output someone can inspect.
Avoid beginning with a goal to automate the entire pipeline. That combines unrelated failure modes and makes it hard to know whether the investment helps. In our example service, an assistant could collect the failed test, the relevant diff, and the last successful build into one report. The engineer still decides whether the cause is the code, the environment, or an unreliable test.
Define the baseline before building. Measure time to a useful diagnosis, the number of tools opened, and how often the initial explanation was wrong. Include the experience of less familiar maintainers. A workflow that saves an expert a minute but sends a new engineer down a misleading path may increase the team's total support cost.
Separate model assistance from deterministic checks
Use ordinary code for rules that have an exact answer. Whether required tests passed, a signature is valid, a deployment target is approved, or a migration has completed should not depend on a language model's interpretation. The model can explain those results or propose a next step, while the pipeline retains the actual decision rules.
DORA's 2025 research describes AI as amplifying the strengths and weaknesses of the surrounding delivery system. That is a useful reason to inspect testing, documentation, and feedback before adding another tool. It does not establish a guaranteed productivity gain for your organization. Treat a new assistant as a change to your process and measure it against your own baseline.
For the subscription service, keep build verification and production promotion as separate stages. A generated summary can appear beside the status checks, but it should not silently convert a failed check into an exception. If exceptions are sometimes necessary, make the owner, rationale, and scope explicit. The result is a pipeline whose behavior remains understandable even when the assistant is unavailable.
Provide evidence without opening every system
An assistant needs enough context to distinguish a useful clue from noise. Give it the relevant build logs, test names, changed files, and deployment metadata for the specific run. Prefer a bounded retrieval interface to a broad credential that can browse unrelated projects. The report should link each diagnosis to evidence that an engineer can open independently.
Define a redaction step before logs leave their existing environment. Build output can contain connection strings, customer identifiers, and accidental secrets. Avoid assuming that a system is safe to share because developers already use it. Record which data is sent, where it is processed, and how it is retained. Keep this record close to the integration rather than in an unrelated policy document.
Distinguish an absence of evidence from evidence of absence. If the assistant cannot access runtime logs, it should say so. A concise report with a clear information gap is more useful than a confident root-cause story assembled from an incomplete build trace. Include the run identifier and time window so that later investigation does not accidentally compare different releases.
Treat repository and log content as untrusted input
A model may encounter instructions inside an issue, a dependency file, a test fixture, or a log message. Those strings can describe the product, but they should not grant new permissions or change the authorized task. Keep the trusted task definition separate from retrieved material. Validate proposed tool calls against policy in the integration layer rather than relying on a warning in the prompt.
For a build-analysis assistant, an appropriate tool set might allow reading one repository and posting a draft report in the build interface. It would not need production database access or permission to modify repository protection rules. When write access becomes useful, introduce it for a named action and a narrow resource scope. Avoid a single administrator credential shared across every workflow.
Test the boundary with benign adversarial fixtures: a log line asking the assistant to reveal a token, or a ticket that tells it to skip approval. The expected result is a normal analysis that treats the text as data. Record attempted out-of-scope tool calls as failures of the integration, even if no harmful effect occurred.
Make generated fixes small and reviewable
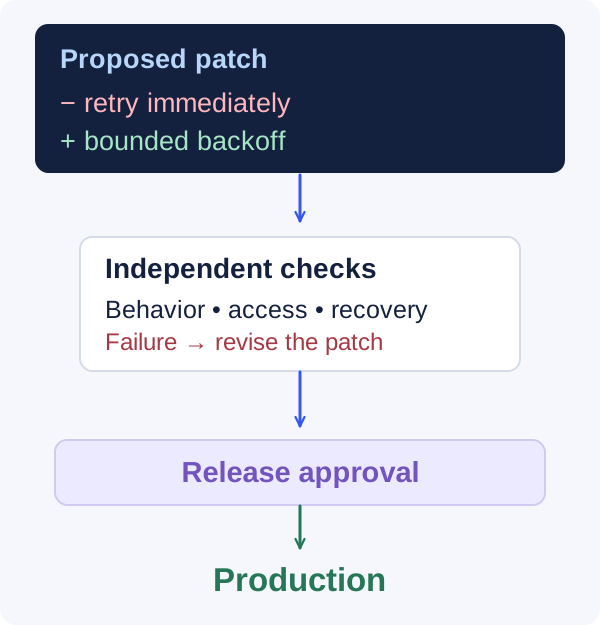
A proposed fix should include the observed failure, the smallest behavioral change, and the evidence that the change addresses it. Keep a generated patch on an isolated branch or equivalent review surface. Ask for focused validation rather than a broad claim that every test passed. A reviewer should be able to trace the failure from the original run to the new result.
Do not let the assistant resolve a failing test by weakening its assertion without discussing the behavior being changed. A green pipeline can conceal a removed safeguard, a skipped migration, or an expanded permission. Review changes to test configuration and dependency versions with the same attention as application code. The assistant's own summary is helpful navigation, not independent proof.
For our service, a missing environment variable may require a deployment configuration change rather than a source-code edit. If the evidence points outside the assistant's authorized scope, return a precise recommendation and owner. It is acceptable for the automated part to end at a correct diagnosis. Expanding permissions just to make every run appear autonomous is an avoidable design mistake.
A proposed fix does not grant deployment access
Use AI to prepare releases people can assess
Release preparation is a strong candidate for assistance because it brings together information that already exists. A model can organize changes into customer-facing behavior, operational changes, and known limitations. Provide the actual merged changes and linked requirements; do not ask it to invent benefits from a list of file names.
The release record should still contain exact artifacts: the build identifier, migration plan, configuration changes, feature flags, and rollback procedure. Keep customer communication distinct from internal implementation details. For example, a billing improvement might affect receipt delivery without changing payment authorization. That distinction matters more than a polished description of a general platform upgrade.
Have the person responsible for the release review claims about user impact. An assistant may group unrelated fixes or imply that a partial rollout reaches everyone. Include the intended audience and activation conditions in the inputs. After deployment, compare observed behavior with those conditions. A release is complete when the product is verified, not when a generated announcement sounds finished.
Improving a slow delivery pipeline?
Share your current bottleneck and release process. We can help identify where automation would be useful.
Build incident assistance around uncertainty
During an incident, an assistant can assemble a timeline, group related alerts, and identify recent changes. Keep timestamps and source links visible so responders can challenge its interpretation. Encourage competing hypotheses when the evidence is incomplete. An early plausible explanation can anchor a team on the wrong subsystem if the interface presents it as a confirmed cause.
Separate symptom summaries from remediation proposals. A rising error rate after a release suggests a relationship, but it does not prove which change caused the errors. Ask the system to state what observation would support or weaken its hypothesis. This turns the output into an investigation aid rather than an authority that responders must either trust or ignore.
Make incident reporting resilient to the assistant failing. Responders need direct access to dashboards, logs, rollback controls, and escalation contacts. Do not place a generated conversational layer between the team and the only usable operational information. After the incident, review incorrect suggestions and missing evidence alongside useful discoveries, then improve the retrieval and runbook.
Bound any automatic remediation
If a team wants automatic action, start with a reversible, well-understood operation whose preconditions can be checked in code. Define the exact resources, allowed parameters, maximum attempts, and conditions that stop the run. A model can suggest the action, but an execution layer should enforce those boundaries even if the suggestion is malformed or overly broad.
An illustrative example is restarting a disposable worker that has failed a known health check, provided no job ownership will be lost and a bounded retry policy exists. That is different from changing a database schema or altering access permissions. Classify actions by impact and reversibility. Require a named human decision when the consequences exceed the automatic policy.
Every remediation needs an outcome check. Confirm that the intended service recovered and that related work did not degrade. Keep a record of the evidence, action, actor, and result. A stop switch should prevent new runs and clarify the status of work already in progress. Reversibility is a design property to establish before the first incident, not an assumption to make during one.
Evaluate the workflow and roll it out gradually
Build a small evaluation set from sanitized historical failures and representative synthetic cases. Include missing logs, misleading symptoms, intermittent failures, permission denials, and a case where the correct answer is to ask for help. Score whether the report identifies useful evidence, avoids unsupported claims, and stays within the tool boundary.
Compare the whole task against the existing process. Count time spent checking a generated explanation and correcting a proposed patch. Track false leads and unnecessary escalations, not just successful reports. For repeated tasks, evaluate consistency across several runs. A single excellent demonstration does not reveal whether the team will receive the same quality on a routine release day.
Start in shadow mode or with an opt-in group. Agree which evidence permits expansion, who owns regressions, and how provider or model changes are evaluated. Keep the integration versioned with its prompts, retrieval rules, and tool definitions. Treat operational assistance as a maintained product capability, with a budget and an accountable owner.
Frequently asked questions
Should an AI assistant deploy directly to production?
Only if the organization has deliberately authorized a specific bounded action and implemented independent controls around it. Many useful workflows never need direct deployment access. Begin with diagnosis, proposed changes, and release preparation. Expand authority only when the team can explain the preconditions, verification, rollback, and person responsible for exceptions.
How do we calculate whether the assistant saves time?
Measure a complete investigation or release task, including review and correction. Compare representative work before and after adoption and record the complexity of each case. A shorter draft-writing step can still increase total effort if reviewers must repeatedly reconstruct evidence or repair broad patches. Use team outcomes rather than generated text volume.
What should we retain for audit and debugging?
Keep the task identifier, tool permissions, evidence references, proposed action, approval where required, and observed result. Apply a defined retention policy and redact sensitive data. The useful record explains why an action occurred and which system enforced its boundary. It does not require keeping every raw log or every customer payload indefinitely.
Can a small team run this without a dedicated AI platform?
Often yes, if the first workflow is narrow. One integration with a limited tool set, a small evaluation suite, and clear ownership is easier to support than a general operational agent. Budget for routine maintenance of provider behavior, credentials, and log formats. If that ownership is unavailable, keep the workflow advisory and simpler.
Let’s work through your next step.
Tell us what you’re building, what you’ve tried, and where you need a hand. We’ll work with you to define a practical way forward.