A live status badge is easy to demonstrate. A real-time product becomes difficult when two people change the same record, a phone loses its connection, and a delayed update arrives after the screen has already moved on. The engineering problem is to keep the experience understandable while the network behaves imperfectly.
Consider an illustrative dispatch application: an operator assigns a delivery, a driver accepts it, and a customer watches its progress. Each person needs different information, permissions, and timing. A location marker may tolerate a missed intermediate update; a change to the assigned driver cannot. This guide explains how to separate those requirements, choose a transport, recover from interruptions, and operate the feature after launch. The recommendations are a starting design process, not a promise about the capacity of any particular stack.
Key takeaways
- Define freshness and correctness separately for each event.
- Keep durable business state outside transient connections.
- Design replay, permissions, and slow-consumer behavior before scaling.
Define what real time means for the user
Start with a table of user actions and the information each action changes. For the dispatch example, accepting a job changes ownership, while sending a location updates a moving estimate. Write down how late each update can be before someone makes a wrong decision. A vague requirement such as instant updates hides these differences and makes every event equally expensive to deliver.
Describe the interface when information is stale. A customer may need a last-updated time, an operator may need a retry option, and a driver may need confirmation that acceptance reached the server. Avoid a single green connection dot as the entire status model. A connected socket does not prove that a business transaction succeeded or that every subscription is current.
Finally, decide what you will measure. Separate server processing time, event delivery delay, and time until the browser renders a usable result. Include the person waiting for confirmation. A backend metric can look healthy while a device queues events behind a busy main thread. Establishing these distinctions gives designers, engineers, and stakeholders a common definition of success.
Choose polling, server-sent events, or WebSockets
Polling is a sensible baseline for infrequent changes. The client requests current state on a schedule, and ordinary request handling remains easy to observe. Its trade-off is repeated work and a delay determined partly by the interval. Before replacing it, measure whether those costs actually matter to the product. An internal report refreshed occasionally does not automatically need a persistent channel.
Server-sent events provide a server-to-browser stream; WebSockets allow communication in both directions. MDN documents these capabilities and the browser APIs. For our dispatch product, customer status updates could use a one-way feed, while a collaborative operations tool might justify bidirectional messages. Neither transport replaces the need to authorize actions, retain state, or recover missed updates.
Prototype the full connection path through the hosting provider, load balancer, proxy, and browser. Investigate idle timeouts and connection limits in the services you actually use. Compare operational complexity with the simpler request-based option. The best decision is the one whose failure behavior your team can explain, not whichever protocol produces the most impressive demonstration.
Give events an explicit contract
An event should say what happened without forcing every consumer to reconstruct the producer's internal implementation. Define a type, a stable identifier, a resource identifier, an occurrence time, and a version of the relevant state. Include only the data the subscriber needs. Large payloads containing whole records increase bandwidth and can expose fields that the interface never intended to show.
For example, a delivery-assigned event can identify the delivery and its new assignment version. A consumer can compare that version with the state already displayed. If an older update arrives later, the application can ignore it or request a fresh snapshot. Do not rely on timestamps alone to settle conflicting changes when ordering matters; clocks and concurrent writes make that assumption fragile.
Treat event changes like API changes. Document whether a field is optional, how consumers handle unknown event types, and how long older clients remain supported. Mobile applications may stay installed for months, and browser tabs can remain open during deployments. A small contract test between producers and consumers often prevents a breaking change that isolated unit tests would miss.
Keep the database authoritative
The durable record should decide whether a delivery is assigned. A socket message is a delivery mechanism, not the source of business truth. Have the server validate the caller, check the current version, apply the transaction, and then communicate the committed result. Optimistic interfaces can show a pending state, but they need a clear response when the server rejects the change.
Consider the gap between committing a database transaction and publishing its notification. If the process crashes in that gap, the assignment exists but subscribers may not hear about it. One design is to record an outgoing event alongside the transaction and publish it through a separate worker. This adds moving parts, so choose it for events whose omission would cause a meaningful problem.
The important requirement is recoverability rather than a particular pattern. An operator should be able to reload a delivery and see the correct committed state even if notifications failed. Build reconciliation around that authority. Avoid having the browser invent its own final answer from a series of transient messages when a reliable server snapshot is available.
Design reconnection as a normal user journey
Connections will drop during network changes, device sleep, deployments, and proxy timeouts. Write the reconnection sequence before building elaborate animation. A useful sequence is to show that updates are paused, reconnect with bounded backoff, re-establish authorized subscriptions, and reconcile against current state before announcing that the screen is live again.
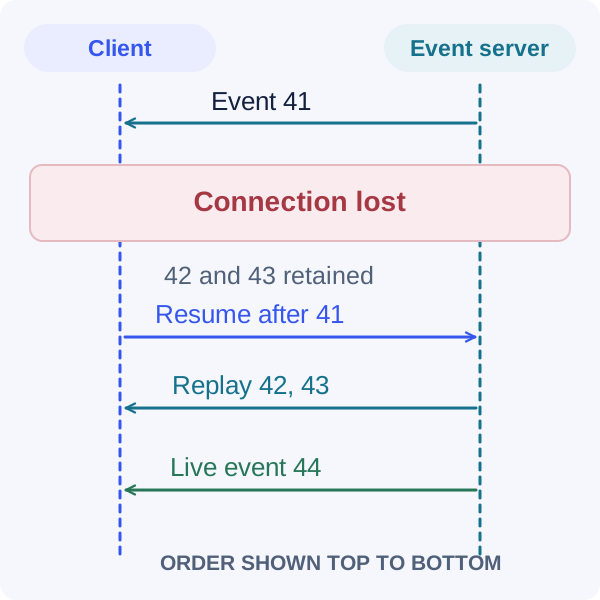
If your system retains events, a client can supply its last processed event identifier and ask for the missing range. Define what happens when that range has expired: usually the server supplies a fresh snapshot and a new cursor. The snapshot and subsequent stream must have a clear boundary so that updates are neither silently skipped nor applied twice during the transition.
Test the pending-action case separately. A driver might press Accept, lose connectivity, and never receive the response even though the server committed the assignment. Retrying with the same operation identifier should let the application discover the original result. Showing a confident failure message without checking can lead a person to repeat work or accept a different job.
Reconnect from the last event you processed
Handle duplicates, ordering, and competing edits
Assume important messages can be observed more than once. Give consumers a way to recognize repeated events and make business operations safe to retry. A duplicate location sample may be harmless; a duplicate charge or notification to a customer may not be. The idempotency rule belongs near the business action, where the system can check whether the effect already occurred.
Ordering is usually meaningful within a resource or conversation, rather than across every event in the company. For our example, maintain a delivery revision that changes when its assignment or status changes. Reject updates based on an outdated revision, then return enough current information for the user to resolve the conflict. A silent last-write-wins policy can erase a valid decision.
Collaborative text editing introduces a different class of problem. If people must edit the same document simultaneously while offline, evaluate conflict-resolution approaches against those exact requirements. Do not introduce a specialized collaboration engine for a status dashboard that only needs current values. Match the consistency mechanism to the operation, and show conflicts in language that explains what a person can do next.
Building a shared, live experience?
Bring your freshness requirements and the actions that must stay correct. We can help plan the architecture.
Protect subscriptions and control overloaded consumers
Authorization must apply to subscriptions as well as writes. A customer who can view one delivery should not receive all events and rely on the browser to hide the others. Resolve the permitted resource set on the server. Revisit subscriptions when roles change, an account leaves an organization, or a session expires. Revocation needs an operational design, not just a login check.
Separate high-value state changes from replaceable updates. If a consumer falls behind on location samples, keeping only the latest position may be appropriate. For assignment changes, preserve a recoverable sequence or force reconciliation. Bound queues so that a slow device cannot accumulate unlimited work. MDN notes that the traditional browser WebSocket API lacks built-in backpressure; your application still needs a strategy for load.
Use per-account and per-connection limits that reflect the product. Observe rejected subscriptions, repeated reconnects, and oversized messages. Log enough context to investigate an error without placing private message bodies or credentials into routine logs. These controls should remain effective when a user opens several tabs or a mobile client reconnects aggressively.
Scale delivery separately from business processing
A connection gateway can manage subscriptions while workers process business events and databases retain state. This separation makes it easier to reason about a traffic burst: are clients reconnecting, workers falling behind, or the database struggling with writes? Adding more gateways will not fix a slow transaction or an inefficient subscription query.
Estimate fan-out explicitly. One event sent to ten subscribers is different from one event sent to every active user. Group audiences around business resources and avoid global broadcasts when the product does not need them. Include serialization, network transfer, retained events, observability, and idle connections in a cost model. A free prototype allowance is not a production forecast.
Edge infrastructure can reduce some network distance, but it does not remove the need to coordinate authoritative state. Identify where writes happen, how regions receive changes, and what users see during regional problems. Start with a topology your team can operate. Expand only when measured latency, resilience requirements, or audience location justifies the additional consistency and deployment work.
Test failures and plan a staged release
Build a test matrix around behavior that people can observe. Disconnect immediately before an action, immediately after it commits, and while the client is reconciling. Deliver the same event twice, reverse two updates, expire a session, and simulate a slow consumer. Check the visible result and the stored record, not just whether a reconnect callback ran.
Run a load exercise that resembles your traffic. Include quiet connections, bursts to popular resources, and reconnect waves after a gateway restart. Watch memory, queue depth, database contention, and delivery delay together. If the system fails, record which limit protects it and whether users receive a useful explanation. A stress test without a recovery observation is incomplete.
Release to a bounded audience with a fallback appropriate to the feature, such as polling or manual refresh. Name the owner of delivery alerts and document how to pause the stream without disabling ordinary business actions. After rollout, compare freshness and error rates with the baseline. Keep the simpler fallback until the team has evidence that normal disruptions are handled correctly.
Frequently asked questions
Does every modern web app need WebSockets?
No. Start with how often information changes, who initiates the update, and what delay users can tolerate. Polling or server-sent events may serve the workflow with less operational complexity. Choose WebSockets when bidirectional interaction is a real requirement and the team can support connection lifecycle management, authorization, and recovery.
Can a real-time connection guarantee that no updates are lost?
The connection alone cannot establish that guarantee. You need durable state, identifiers, retention or snapshots, and a recovery process. Define the business result you need rather than promising perfect transport. In many products, reconciling to an authoritative current record is more valuable than replaying every intermediate visual update.
How should we show offline changes?
Distinguish local pending work from server-confirmed work. Explain whether the action will retry automatically, whether it can conflict, and how the person can cancel it. Give retries a stable operation identifier. For consequential actions, check the server result before telling someone to repeat the operation after a timeout.
What should a first production milestone include?
Choose one event family and one audience. Ship the complete path: authorization, committed state, delivery, a visible stale state, reconnection, and an operator runbook. Include a test that interrupts the connection mid-action. Broader fan-out and additional event types can follow once the first path behaves predictably under real conditions.
Let’s work through your next step.
Tell us what you’re building, what you’ve tried, and where you need a hand. We’ll work with you to define a practical way forward.