Micro-frontends are worth considering when stable product teams need to release different areas independently. Begin with a modular application if the same team owns every area or changes frequently cross the proposed boundaries. Splitting the frontend only helps when the new boundary removes a coordination problem.
This guide uses an illustrative ordering and reporting platform to compare composition models and define a release contract. You can use the tables to choose a pilot route, decide how navigation and identity cross its boundary, and test whether an independent deployment remains compatible with the application already open in a customer's browser.
Key takeaways
- Choose boundaries around independently owned business capabilities, not individual interface components.
- Write down the shell, navigation, identity, and release contracts before choosing integration technology.
- Keep server-side authorization authoritative even when several frontend applications share a session.
- Pilot one route and measure whether independent delivery actually improves the team’s work.
Start with the coordination problem
List the release problems you want to solve. Perhaps the reporting team waits for checkout regression testing, or a shared application takes so long to build that small changes spend a day in queues. Separate symptoms from causes. A slow pipeline may need caching; unclear ownership may need a team agreement; a tangled dependency graph may need better modules inside the existing application.
Measure a baseline before changing architecture. Record time from approved change to production, how often unrelated teams must approve a release, and how many incidents come from integration between domains. These measurements give you a way to judge the migration later. Counting repositories or deployment jobs says little about whether work became easier.
Micro-frontends become a stronger candidate when domains have stable owners, substantially different release rhythms, and a limited need for shared state. They become a weaker candidate when features regularly span every domain. For the example platform, independently maintained reporting could be a sensible starting point, while splitting an order form into separately deployed line items would create a boundary inside a tightly connected interaction.
Draw business boundaries before repository boundaries
A useful boundary encloses a coherent user task. Ordering includes searching products, editing quantities, validating availability, and submitting an order. Reporting includes selecting a period, applying filters, and exporting results. Each can have internal components without turning every component into its own application.
Write a short contract for each domain: the routes it owns, the APIs it consumes, the events it publishes, the permissions it requires, and the team responsible for incidents. Identify shared concepts such as customer, organization, and subscription. Agree on identifiers and vocabulary before those concepts acquire different meanings in different applications.
Repository structure comes afterward. A monorepo can contain independently deployable applications, while multiple repositories can remain tightly coupled through synchronized releases. Choose the arrangement that makes dependency changes, local development, and code ownership manageable. Independence is a property of contracts and deployment behavior, not the number of Git repositories.
Also document the boundary’s likely lifespan. A short-lived experiment may deserve a simpler integration than a core domain expected to remain independently owned for years.
Choose an integration model that fits navigation
Choose the composition model from the interaction you need to preserve. Route-level composition gives an entire task to one application. Runtime composition brings separately loaded components into the same document. An iframe gives an embedded application its own document boundary. Each changes how navigation, shared state and failure must be handled.
Next.js multi-zones use separate applications for different paths on one domain. A transition across zones reloads the document; links across that boundary use ordinary anchors rather than Next.js client navigation. Keep frequently connected screens in the same zone and give zone assets distinct prefixes to prevent collisions.
For the illustrative platform, a saved report can live at /reports/orders?customer=example while the ordering flow stays together. Treat the query parameter as untrusted input and authorize the report on the server. Prototype opening that report, returning to the filtered order list and using the back button before committing to a loader or repository split.
| Approach | Useful boundary | Cost to verify |
|---|---|---|
| One application with modules | One team owns ordering and reporting; changes often span both. | Module ownership and dependency rules; one coordinated deployment. |
| Route-level applications | Reporting has its own owner and release schedule; a document reload is acceptable. | Route and asset ownership, deep links, session continuity and back navigation. |
| Runtime component composition | Separately owned areas must interact within one continuous screen. | Shared dependencies, compatibility, loading errors and cross-component state. |
| Embedded document | A separately operated reporting tool needs a contained integration. | Frame sizing, focus, navigation and a narrowly defined message interface. |
Keep the shared shell deliberately small
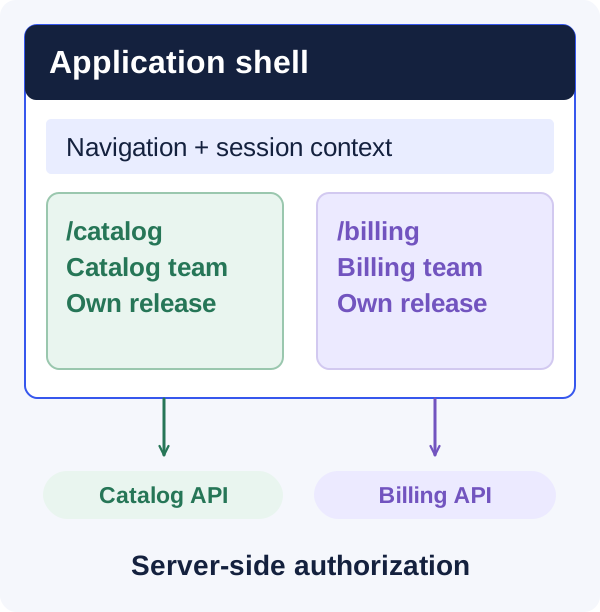
The shell usually owns global navigation, the overall page frame, session entry points, and a small set of platform concerns. Resist placing all business logic in it. A shell that understands every domain becomes the new monolith, only with more deployment steps around it.
Define how applications register routes and describe navigation items. Prefer a documented contract over a shell importing arbitrary internal files from each domain. Decide which team handles a missing route, an unavailable application, and a user who has permission for the platform but not a particular feature.
Shared design tokens and accessible primitives help maintain consistency. Share buttons, form behavior, typography, and spacing where that reduces duplicated decisions. Avoid a universal component package that contains every business screen. Its release cadence would force unrelated domains to coordinate again.
Version shared packages and provide a migration window. A shell update should not silently break a domain that has not yet adopted a new component API. Compatibility checks should exercise an older supported domain build as well as the newest build, because production rarely updates every moving part at exactly the same moment.
One shell, independently owned routes
Treat identity as a platform concern and authorization as a server concern
A consistent login experience does not mean every application should receive unrestricted credentials. Decide how sessions are established, refreshed, and ended, and which server-side services validate them. Keep sensitive tokens out of ad hoc browser events and avoid scattering separate authentication implementations across domains.
Every API must still authorize the requested action against the current user, organization, and resource. Hiding a navigation item is a usability choice, not an access-control boundary. A user can call an endpoint directly, and an older application build may display controls that are no longer appropriate.
Test organization switching carefully. A customer identifier cached in one domain must not survive a switch to another organization in a way that exposes the previous organization’s data. Clear or partition caches, cancel outstanding requests where appropriate, and verify that responses are checked against the current context before rendering.
Define logout behavior across open tabs and independently loaded applications. Include expired sessions, revoked membership, and changes in permissions in the integration test plan. These are product flows with security consequences, not merely authentication-library details.
Considering micro-frontends for your team?
We can help review the route contract, team ownership and rollback plan for a bounded frontend pilot.
Exchange small contracts instead of sharing all state
A global mutable store shared by every domain is convenient at first. Over time, it can make independent releases impossible because each application relies on the exact shape and update timing of everyone else’s state. Prefer explicit URLs, server records, and narrow events for cross-domain communication.
For example, an order-created event can contain an order identifier and schema version. Reporting can refresh its own view rather than receiving the entire ordering application’s internal object graph. A link to a report can carry stable query parameters that are validated by the receiving application.
Name events according to completed facts rather than commands with ambiguous ownership. State whether delivery is best effort and whether consumers must retrieve current data. A browser event bus is not a durable transaction log; a tab can close before another application observes a message.
Use contract tests for shared payloads and routes. Include missing fields, an unknown event version, and identifiers that no longer exist. If two domains need to coordinate every keystroke, reconsider whether they should be separate applications at all. Close coupling in the user interaction usually needs close coordination somewhere in the architecture.
Budget for performance and partial failure
Independent applications can accidentally ship repeated libraries, fonts, styles, and analytics. Establish a page-level performance budget rather than allowing every team to optimize only its own bundle. The user downloads the combined result and experiences the slowest critical dependency.
Measure initial loading, route transitions, layout movement, and input responsiveness on representative devices. A powerful development laptop conceals problems that appear on an older phone. Check whether shared dependencies genuinely reduce transferred bytes or simply move complexity into a runtime loader.
Design failure states for a domain that cannot load. The rest of the platform should remain understandable, and users should have a route back to working areas. Do not leave an empty region where a payment form or report should be. Explain whether the user’s work is saved and offer a controlled retry.
Set timeouts and ownership for error reporting. A shell-level incident should identify the failing domain and deployed version without collecting sensitive page content. Teams need enough evidence to diagnose their application, while the platform owner needs a view of the overall customer experience.
Make independent deployment demonstrable
Prove independence by releasing reporting without rebuilding ordering. In this illustrative pilot, the reporting team owns /reports/* and its assets; the platform team owns the gateway and session entry points. The reporting API continues enforcing resource permissions even when the shell has already checked the login.
Record the contract below in the repository, then rehearse a new reporting release against the shell version already in production. This is a sample agreement, not a universal compatibility window. Choose the overlap from session length, deployment cadence and operational capacity.
Rollback must restore a compatible frontend and API combination. If a data migration prevents the prior build from working, a frontend rollback alone cannot recover the feature. Keep older assets available for the agreed overlap and test a tab opened before deployment as well as a fresh session.
| Contract | Decision to record | Verification |
|---|---|---|
| Routes and assets | Reporting owns /reports/* and a distinct reporting asset prefix. | Direct deep links, missing routes and asset loading work through the gateway. |
| Context | Customer selection travels in the URL; report data comes from the reporting API. | Changing organization cannot expose a previous organization's report. |
| Compatibility | Support the documented current and previous shell builds during the release overlap. | Deploy reporting against both supported combinations without rebuilding ordering. |
| Recovery | Name a rollback owner and keep compatible API behavior and versioned assets. | An existing browser tab still loads; a reverted release can read current records. |
Migrate one route with a clear stop condition
Choose a low-risk, well-bounded route with a real owner. Extract it behind the existing navigation, preserve its URL where possible, and compare behavior before and after. Start with a useful vertical slice that includes loading, authorization, errors, monitoring, and deployment rather than an empty application scaffold.
Keep the old implementation available during a controlled transition if the data model permits it. Define which users see the new route and how to return them to the old experience if problems appear. Avoid two writable implementations that can update the same records differently without a reconciliation plan.
Evaluate the pilot against the original coordination problem. Did release lead time improve? Are support incidents easier to assign? Did page performance or accessibility regress? How much extra platform maintenance appeared? These observations are more useful than declaring the architecture successful because the extracted route renders.
Set a stop condition as well as a success condition. If the new boundary requires constant synchronized changes, fold it back into a modular application or redraw it. A reversible pilot is a better engineering investment than a migration that must continue simply because several repositories now exist.
Create an ownership agreement teams can actually use
Before expanding the approach, write a one-page operational agreement. Name the owner of the shell, each domain, shared identity, and design foundations. State who responds when the overall page is broken but each application’s isolated checks pass. Ambiguous incident ownership is one of the fastest ways for organizational boundaries to become customer problems.
Include the release notice period for breaking contracts, the supported compatibility window, and the process for removing old assets. Explain how teams propose a shared component without requiring a committee for every visual adjustment. The agreement should help someone make a decision during ordinary work, not merely document the ideal architecture.
Review it after the first few independent releases. If exceptions are frequent, the contract may be wrong rather than the teams being undisciplined. The objective is a platform where product areas can evolve predictably while the user still experiences one coherent service.
Frequently asked questions
Should a startup begin with micro-frontends?
Usually only when there is an unusually strong organizational or integration reason. A small team can often move faster with one application containing clear internal modules. Preserve domain boundaries in code, then extract a domain when independent ownership and release needs become concrete. Starting with the most distributed option makes every early product change pay an integration cost.
Do micro-frontends require different frameworks?
No. Teams can use the same framework and still deploy independently. Supporting multiple frameworks may help during a migration, but it adds dependencies, testing requirements, and design-system work. Treat framework diversity as a capability you may need, not a goal that proves the architecture is flexible.
Can micro-frontends improve search visibility?
They do not automatically improve or damage it. Rendering, canonical URLs, metadata, links, status codes, and performance still determine whether public content is accessible to crawlers and useful to visitors. Test those properties at the composed page level. A domain that renders correctly in isolation can still lose metadata or navigation context after integration.
What is a sensible first deliverable?
An architecture decision record and a working pilot route. The record should explain the delivery problem, alternatives, domain contract, failure behavior, and measurement plan. The pilot should prove navigation, authentication, deployment, rollback, and observability. A demonstration that only loads a remote component leaves the most important questions unanswered.
Let’s work through your next step.
Tell us what you’re building, what you’ve tried, and where you need a hand. We’ll work with you to define a practical way forward.