Choose a startup tech stack your team can build, debug and operate while it tests the product's main assumption. For an illustrative SaaS team already comfortable with TypeScript and SQL, a Next.js application, server-side business rules and managed PostgreSQL are a reasonable candidate. Different team skills or product requirements can make another stack the better choice.
The worked decision table below names the responsibilities, alternatives and triggers for revisiting this candidate. The example product tracks customer requests for several organizations and needs accounts, workflow, notifications and reporting. It does not need multiple frontend deployments or a fleet of services to discover whether customers value that workflow.
Key takeaways
- Choose tools the team can build, debug, deploy, and maintain—not only demonstrate.
- Use one dependable default for each major responsibility until a specific requirement justifies another.
- Keep business rules and data ownership clear so vendor changes remain manageable.
- Evaluate the cost of operations, migration, and failure alongside initial implementation speed.
Write down the constraints that actually matter
Begin with the product’s essential tasks, expected users, data sensitivity, integrations, and release needs. Add team skills, available engineering time, and the people responsible for support. These constraints are more useful than a list of technologies used by successful companies with very different resources.
Separate known requirements from assumptions. A confirmed need to process large media files matters today. A possibility that the product might one day support millions of concurrent users is a planning hypothesis. Preserve an expansion path without paying the full complexity cost before demand exists.
Identify the hardest requirement early. It might be an external system with a limited API, an offline mobile workflow, a specialized calculation, or a customer’s security expectations. Build a proof around that requirement before choosing the rest of the stack by preference.
Record what the team is willing to outsource to managed services and what must remain under direct control. The answer can differ across authentication, payments, search, hosting, and data storage. A coherent stack reflects those decisions rather than accumulating tools one tutorial at a time.
Choose the frontend around the interaction model
A public content site, an authenticated dashboard, and a highly interactive editor have different rendering and state needs. Decide which pages need fast first access, which content should be discoverable through search, and which interactions require substantial client-side behavior.
Use a framework that supports the product’s actual delivery model and that the team can debug. Evaluate routing, forms, loading states, error boundaries, accessibility, and deployment—not only component syntax. A familiar framework with clear conventions can be more valuable than a newer option that introduces unresolved operational questions.
Keep client state purposeful. Server records, temporary form input, navigation state, and cached results are different categories. Treating all of them as one global store can create confusing synchronization and ownership problems. Start with the simplest state approach that keeps the important workflows understandable.
Build a representative screen with real validation and error behavior before finalizing the frontend foundation. The exercise should reveal how the team will handle ordinary product complexity, not merely prove that a development server can render a polished landing page.
Prefer a backend the team can reason about
For the illustrative TypeScript team, keep the request workflow, membership checks and entitlements in server-side modules with one primary data model. Next.js can provide the web interface and server entry points; use a separate Node service only when a concrete workload or deployment boundary justifies it. A team experienced in Django or Rails can apply the same design using its existing tools.
The hosting choice must match the code. A static export suits public content but cannot execute a live authenticated server workflow by itself; Next.js self-hosting supports server deployment patterns with their own operating responsibilities. Run slow imports and notifications through explicit background jobs rather than leaving them attached to a request that can time out.
PostgreSQL transactions can group related database changes into an all-or-nothing unit. They do not include an external payment provider or email service automatically. Record durable work and design retries for those boundaries. The table is an engineering starting point under the stated assumptions, not a best-stack ranking or a cost benchmark.
| Responsibility | Candidate and ownership | Change the choice when… |
|---|---|---|
| Web application | Next.js and TypeScript; one application with domain modules and server authorization. | The team has stronger existing skills elsewhere, or the main product is an offline mobile workflow. |
| Primary records | Managed PostgreSQL; versioned migrations, tenant constraints and restore ownership. | A measured access pattern needs a specialized store; keep the source of truth explicit. |
| Identity | A reviewed identity provider; the application still owns membership and permissions. | A customer requirement is unsupported by the provider's actual configuration or agreement. |
| Files | Object storage with server-authorized upload and download paths. | Retention, processing or access requirements exceed the service's verified capabilities. |
| Background work | A durable queue and worker for imports and notifications. | Measured execution limits or independent workload needs justify a separate service. |
| Delivery and operations | Managed server deployment, separate environments, error monitoring and rehearsed restores. | Observed constraints justify more operational complexity and the team can own it. |
Choose a data model before choosing specialized databases
List the core entities, relationships, and invariants. For the request-tracking example, organizations own requests, users have memberships, and each request has a history of state changes. Understanding these relationships helps determine which database capabilities matter.
A relational database is a reasonable candidate when relationships, transactions, and structured queries dominate, but the decision should follow the workload. Specialized stores can help with search, analytics, or particular access patterns when there is a concrete requirement. Adding several databases early also adds synchronization, backup, and operational work.
Define identifiers, timestamps, deletion behavior, and organization boundaries consistently. Include migrations in version control and review how changes affect existing records. Development fixtures should include multiple organizations and realistic data volumes so access and performance assumptions can be tested.
Plan export and recovery from the beginning. The team should know how to retrieve customer data in a usable form and restore it in a safe environment. A database choice is not complete until backup, retention, access, and migration responsibilities are understood.
Use managed services with explicit ownership boundaries
Managed authentication, payments, storage, and messaging can save substantial implementation effort. The product still owns how those services fit together. A payment provider does not define your entitlement policy, and an identity provider does not decide which customer records a user may access.
Evaluate each service’s failure behavior, integration model, data export options, and operational visibility. Ask what happens when requests time out, callbacks arrive twice, or the provider is unavailable. The application needs a recoverable state instead of assuming every external request succeeds exactly once.
Keep provider-specific code behind a clear boundary where practical. This does not require building a universal abstraction for every possible vendor. It means avoiding a design in which every screen directly depends on the provider’s internal object shape or status names.
Document the data sent to each service and the credentials required. Use least-privileged access and separate environments. Before adopting a service for sensitive information, review the applicable contractual and technical requirements with the responsible people. Convenience should not create an unexamined data-handling arrangement.
Choosing the foundation for a new product?
We can help turn your team skills and hardest product constraint into a small stack and a reviewable first release.
Make deployment boring before making it sophisticated
Choose hosting that supports the application with a manageable operational burden. A simple managed deployment can be a good fit for a small team. Containers, orchestration, and multi-region infrastructure may become useful, but each should solve a specific requirement rather than signal ambition.
Create a repeatable build and deployment path, separate configuration by environment, and manage secrets outside the repository. A new developer should be able to understand how a change reaches production and how to recover from a failed release.
Use backward-compatible changes where old and new versions may overlap. Database migrations and external integrations need particular care. A rollback button is not enough if reverting the application leaves it unable to read the changed data model.
Keep a short operational runbook covering deployment, logs, backups, common failures, and support escalation. The runbook should be tested by someone other than its author. Early products often depend on a small team, so reducing undocumented knowledge is a direct reliability improvement.
Build the minimum useful quality system
Select checks according to the ways the product can fail. Type checking, linting, and automated tests can catch different problems, but none should become a ceremonial dashboard. Prioritize organization isolation, core business rules, critical integrations, and the main customer journey.
Use realistic test data and include negative cases. A workflow that works for one administrator in an empty account may fail for an ordinary member in an established organization. Permission changes, duplicate submissions, expired sessions, and unavailable services deserve deliberate coverage.
Add observability before customers arrive. Record actionable errors and important workflow events with appropriate privacy controls. The team should be able to distinguish a client error, a failed dependency, and an invalid business request without collecting every sensitive payload.
Choose a small set of release criteria that the team can maintain. The goal is confidence and feedback, not the largest possible toolchain. A reliable short pipeline is more useful than a complex pipeline that everyone bypasses because it is slow or frequently wrong.
Account for AI features without redesigning everything around them
If the product needs AI, identify the specific task and the information required. Classification, extraction, grounded answers, and multi-step actions have different engineering needs. Do not introduce an agent framework simply because the product includes a model call.
Keep model access behind a server boundary that handles credentials, permissions, budgets, and diagnostics. Define what the application does when the model is unavailable, too slow, or produces an unusable result. Critical business rules should remain enforceable without asking the model to interpret them.
Version prompts and evaluation cases alongside the feature. Measure task success and cost using representative inputs before increasing autonomy or usage. The model provider, retrieval system, and tool interfaces can evolve independently if their responsibilities remain clear.
Avoid locking the entire product to an experimental integration without understanding an exit path. You do not need perfect provider interchangeability, but you should know which data, prompts, tools, and user experiences would need to change if the current approach stops meeting the product’s requirements.
Estimate total cost and switching cost honestly
Compare implementation time, recurring service costs, operational effort, and the consequences of failure. Free tiers and introductory credits can help experimentation, but they are not a complete forecast. Model usage at a few plausible customer levels using current provider terms.
Consider the cost of changing each decision. A component library may be relatively easy to replace; a data model embedded in every integration may be much harder. Spend more design attention on difficult-to-reverse decisions while allowing reversible implementation choices to remain simple.
Avoid both extremes of vendor dependence. Refusing every managed service can force a small team to build undifferentiated infrastructure. Ignoring export, contracts, and data ownership can make a later change unnecessarily painful. Choose dependence knowingly and document the trade-off.
Review the cost model after the first real customers arrive. Actual workloads often differ from forecasts. Use that evidence to optimize or change services rather than treating the initial stack as either sacred or a mistake that must be completely replaced.
Capture the decision and define when to revisit it
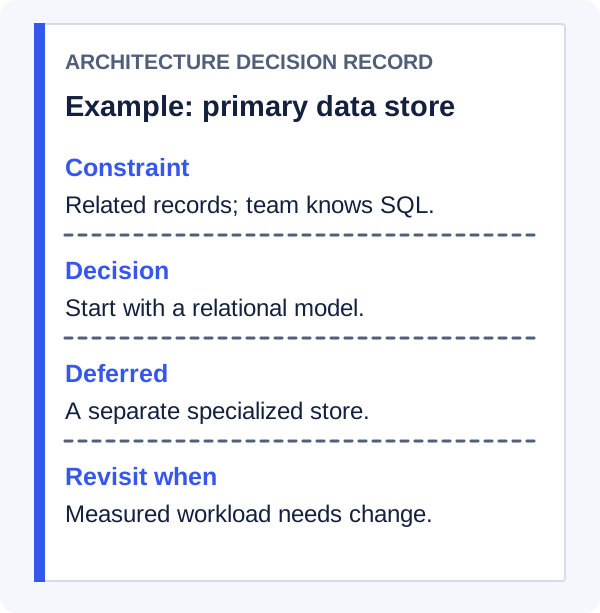
Write a short architecture decision record for each consequential choice. Include the problem, constraints, selected approach, alternatives, and known limitations. State what evidence would justify reevaluation, such as a measured bottleneck, an unsupported integration, or a significant change in team structure.
Revisit decisions at product milestones rather than reacting to every new release announcement. A startup benefits from tools that remain understandable while the product itself changes rapidly. Switching frameworks without a concrete constraint can consume the same capacity needed to learn from customers.
For the request-tracking example, a sensible first stack might remain intentionally ordinary while the workflow develops. Later, search or analytics can be extracted when the workload warrants it. The durable investment is clear business logic, reliable data, and a team that can operate the product—not a claim that the original technology choices will never change.
Turn architecture decisions into a bounded MVP delivery plan
Keep the reason for a stack decision
Frequently asked questions
What is the best startup stack in 2026?
There is no single best stack independent of the product and team. Start with requirements, existing skills, integrations, and operational responsibility. Choose a small set of well-understood tools and validate the hardest requirement early. A defensible decision is more useful than copying a popular stack without its original context.
Should we use microservices from the beginning?
Only when a concrete requirement justifies their coordination and operational cost. A modular application can preserve useful boundaries while keeping deployment and debugging simpler. Extract services when independent scaling, ownership, or reliability needs are demonstrated rather than assumed.
How much future scale should we plan for?
Protect core data integrity, access boundaries, and migration paths from the beginning. For capacity, design around a plausible near-term workload and identify how to measure bottlenecks. Avoid building an expensive distributed system for demand that has not been validated. Scalability includes the team’s ability to operate the system.
Can we change the stack after launch?
Yes, but the cost depends on the boundaries you establish. Clear APIs, documented data models, export capability, and isolated provider integrations make changes easier. Prefer incremental replacement of a demonstrated constraint over a complete rewrite driven by dissatisfaction with the age or fashion of the current tools.
Let’s work through your next step.
Tell us what you’re building, what you’ve tried, and where you need a hand. We’ll work with you to define a practical way forward.